Genomics Pipelines, Tools, and Hackathons
A list of my genomics pipelines and tools developed at OPBG, SCRI, Fred Hutch, and through external collaborations, such as Hackathons. These pipelines and tools were used to reproducibly process data or generate figures for many of the published journal articles on projects I supported.
Genomics Data Pipelines
1. Somatic Variant Detection and Clinical Filtering
- Nextflow DSL2 pipeline developed at OPBG to detect and annotate somatic variants from long-read whole genome sequencing for a retrospective cohort of over 100 T-cell acute lymphoblastic leukemia (T-ALL) patients.
Show Details
Structural variants are called with an ensemble of
Severus,SAVANA, andMINDA. Each caller was benchmarked against the others before integration to select the strongest method for the sample type.Single nucleotide variants are called with
CLAIR3, and copy number alterations are detected from the same aligned reads, so that SV, SNV, and CNA evidence is produced in a single pass.Annotation and clinical filtering use Ensembl
VEP,AnnotSV,ClinVar, andgnomADto prioritize variants of interest and remove common population variation.Replaced manual curation of three variant detection methods across two sequencing technologies (DNA WGS and RNA-seq fusions).
Variant calls are surfaced to investigators through interactive Quarto dashboards, rather than as raw call sets. Each report combines the filtered variants with IGV genomic tracks for read level confirmation and ProteinPaint visualizations for protein domain context, so candidate variants can be reviewed and acted on in one place.
Automated QC and reporting workflows built with Quarto curate the variant and expression outputs and flag outliers or inconsistent samples and batches, shortening the turnaround from pipeline run to actionable result.
2. Long-read Nanopore WGS Processing
- Nextflow pipeline for Oxford Nanopore PromethION whole genome sequencing, deployed on the OPBG on-premise cluster and on the PromethION instrument server.
Show Details
Produces structural variants and single nucleotide variants from a single long-read run, enabling rapid turnaround compared to short-read workflows.
Also used to characterize CAR-T vector integration sites in transduced human cell lines, aligning reads to a composite reference and parsing supplementary alignments to identify chimeric read junctions that mark genomic insertion loci.
Software dependency stack (containers and python virtual environments) configured to run the same pipeline reproducibly on both the compute cluster and the sequencing instrument server.
3. Cut and Run Nextflow workflow
- Custom pipeline developed from nf-core workflow template and uses most nf-core best practices.
Show Details
Performs Bowtie2 alignment, quality trimming of reads with trimgalore, SEACR peak calling, and optionally MACS2 peak calling.
MACS2 requires an effective genome size to call peaks, which can be provided directly in
nextflow.configor useunique-kmers.pyto calculate the effective genome size on the fly.Coverage tracks are produced for visualization in IGV.
Performs general QC statistics on the fastqs with fastqc, the alignment, peak calling, and sample similarity using deeptools. Finally, the QC reports are collected into a single file using multiQC.
Documented using parameterized Rmd that knits to HTML and github markdown formats.
CI/CD with Atlassian bamboo agent for functional tests using small toy datasets and to re-build documentation.
Public version can be found here, but most recent releases are private repos at SCRI bitbucket.

4. RNA-seq Quantification Nextflow workflow
- Custom RNA-seq alignment and quantification pipeline developed using nf-core tools and uses most nf-core best practices.
Show Details
Designed to output gene expression counts from bulk RNA-seq using
STARaligner using--quantmode.Performs general QC statistics on the fastqs with
fastqcand the alignment usingrseqc.Finally, the QC reports are collected into a single file using
multiQC.
Documented using parameterized Rmd that knits to HTML and github markdown formats.
Public version can be found here, but most recent releases are private repos at SCRI bitbucket.

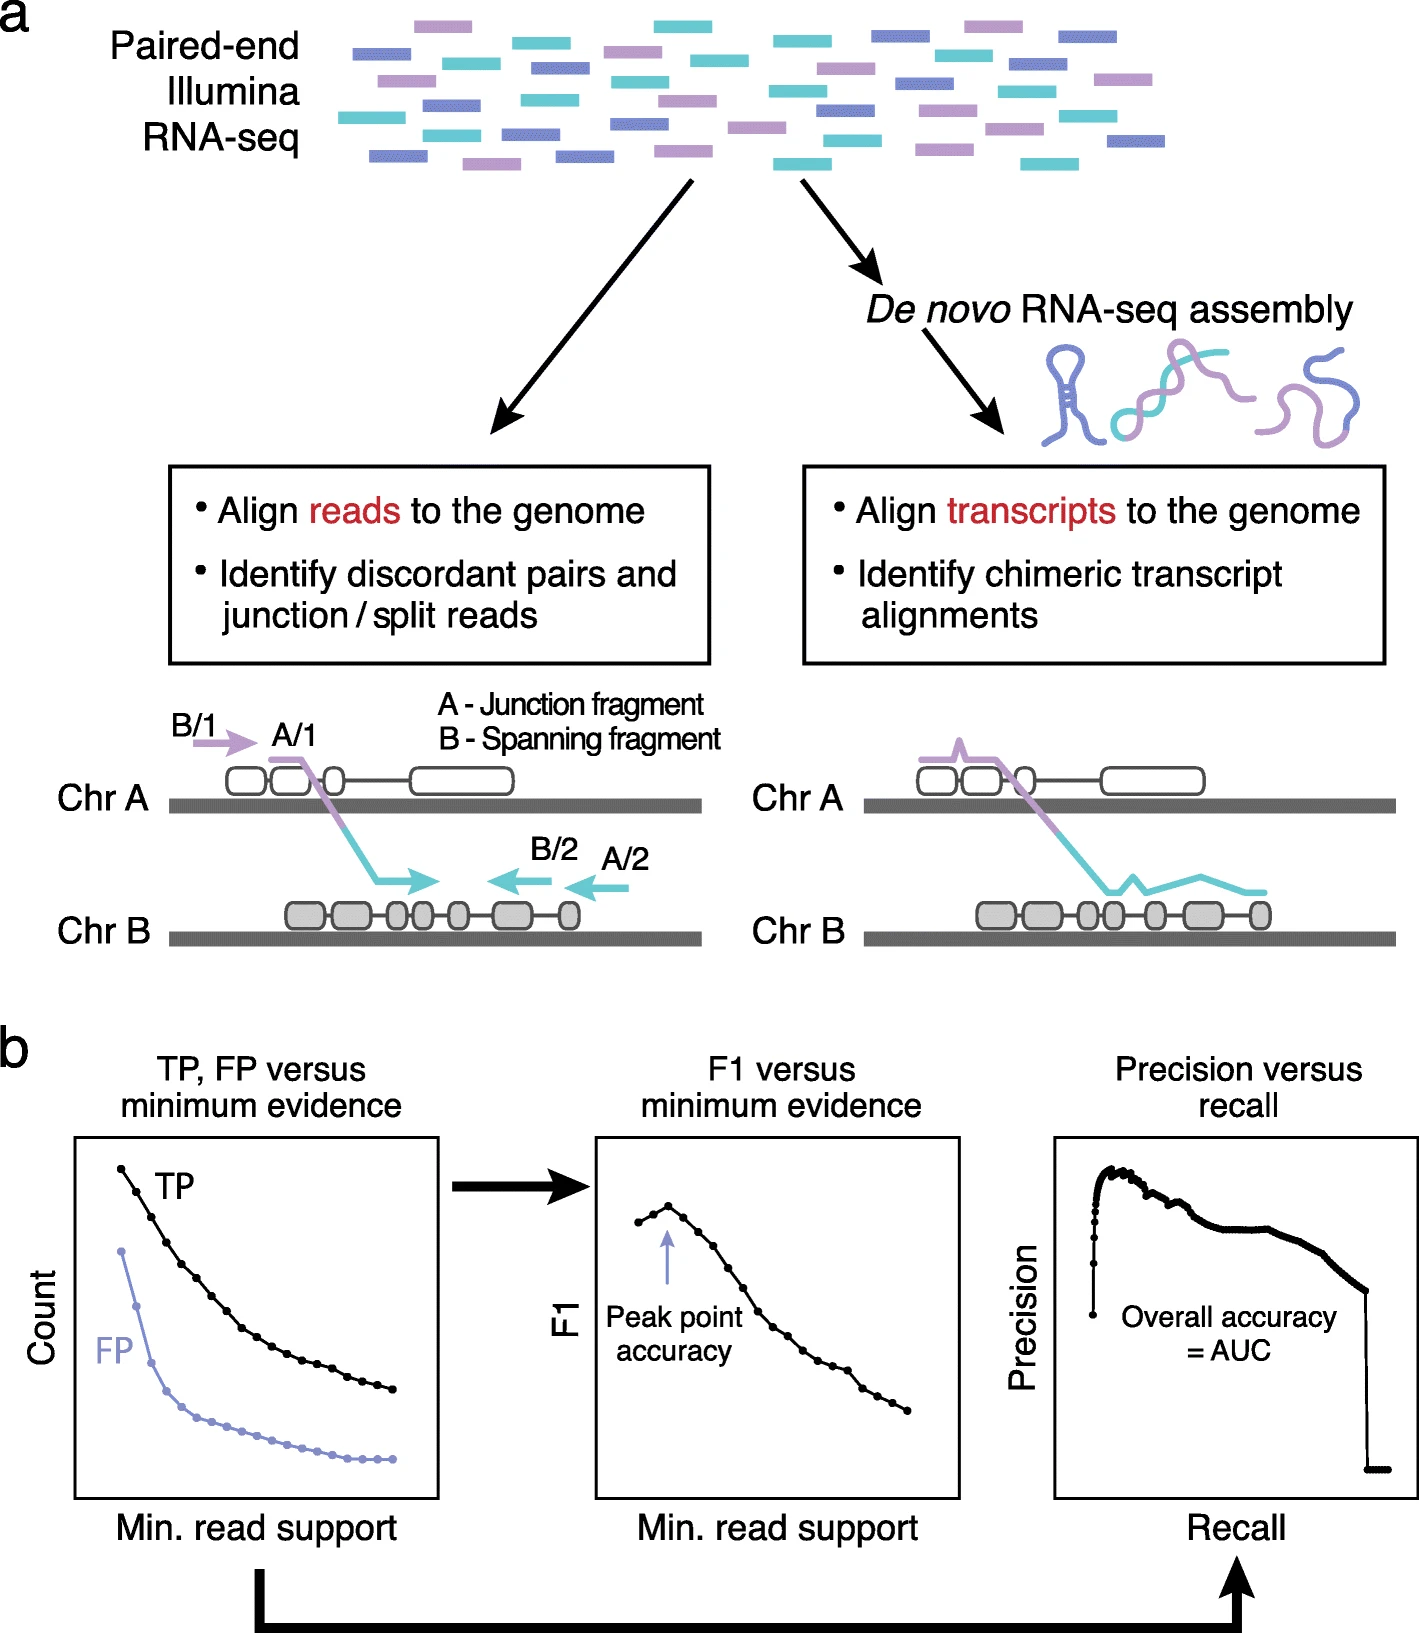
5. RNA-seq Fusion Detection Nextflow workflow
- Custom RNA-seq pipeline to detect fusion transcripts developed using Nextflow DSL2 syntax.
Show Details
Bulk RNA-seq fusion detection pipeline with
STARaligner,STAR-Fusion, andFusion-Inspector. This includes the most relevant output files, such as SJ.out.tab, aligned.bam, and chimeric.junctions.tab, and the fusion inspector HTML report.The workflow also includes the
CICEROfusion detection algorithm that is run using the aligned.bam from STAR-aligner output.In addition, the fastq files undergo quality control checks and a multiQC report.
Configured for SLURM, PBS pro, and AWS batch executors with containerized software. Outputs can be saved locally or configured to upload data to AWS S3 buckets.
Public version can be found here, but most recent releases are private repos at SCRI bitbucket.
Other Pipelines
Other nextflow pipelines generated with nextflow and nf-core tools include:
CutandRun and Chip-seq heatmaps (AKA tornado plots - see Figure below)
VCF variant annotation
splitting ATAC-seq bams by fragment size

Transcriptomics and Single Cell Analyses
Therapeutic Target Discovery in Rhabdomyosarcoma
- Single cell and bulk RNA-seq analysis of pediatric rhabdomyosarcoma (RMS) patient derived xenograft models and OPBG patient cohorts, to identify and prioritize surface antigen targets for CAR-T cell therapy development.
Show Details
Used the Developmental Human Limb Cell Atlas (over 125,000 cells) as a reference for cell type classification, iteratively optimizing label transfer with updated reference PCA dimensions and loadings,
SeuratRPCA based dimensionality reduction for query projection, and marker gene expression withSingleR.Tertiary analysis of the RMS single cell data included UMAP dimension reduction, Leiden unsupervised clustering, and multi-sample integration with RPCA.
Candidate therapeutic target gene expression visualized at single cell resolution across both PDX and healthy limb development samples.
Bulk RNA-seq from primary RMS tumors analyzed alongside the single cell data, using curated metadata including fusion status and clinical covariates, with unsupervised clustering by PCA and heatmaps.
Armored CAR-T Transcriptome Profiling
- Bulk RNA-seq analysis investigating whether a membrane bound IL-15 enhances persistence and infiltration of CAR-T cells directed against the ganglioside GD2 in a neuroblastoma model.
Show Details
Processed and analyzed the full sample set to deliver QC reports, normalized gene expression matrices, PCA, and unsupervised hierarchical clustering.
Executed over 24 differential expression comparisons, including inter- and intra-timepoint contrasts and interaction effect models, followed by GSEA pathway enrichment analysis.
Generated publication quality figures across all primary analyses (PCA, clustering heatmaps, volcano plots, and GSEA enrichment panels), formatted to journal submission standards.
Compute Infrastructure
On-premise Cluster
- Designed, configured, and deployed the laboratory compute infrastructure at OPBG to support high throughput genomic data processing.
Show Details
Configured Ubuntu servers, network attached storage, and a shared file system across nodes with NFS, increasing compute and storage capacity by more than 3x.
Enhanced parallelization by configuring the
HyperQueuejob scheduler, enabling concurrent multi-sample batch processing with both Nextflow and Snakemake.Deployed and validated the genomics pipelines on-premise, configuring the full software dependency stack (python virtual environments and containers) on the cluster and the PromethION instrument server.
R and python environments are restored with
renvandvenvrespectively, so analyses remain reproducible across platforms.
Cloud Platform Evaluation
- Coordinated an evaluation of major cloud providers to identify solutions for genomic workloads that comply with GDPR and Italian health data privacy requirements, in collaboration with OPBG IT.
Show Details
Deployed and benchmarked a test environment for genomic pipeline execution on Google Cloud HPC, validating VM configurations, software dependencies, and pipeline integration.
Deployed test environments on Microsoft Azure, including validation of hybrid on-premise to cloud data transfer.
Collaborated with Amazon AWS solutions architects and biomedical data managers to define HPC service requirements and cost models.
All environments assessed for regulatory compliance with Italian health data privacy frameworks.
CI/CD and Reproducible Development Environments
Use of Github actions and Gitpod with DevContainers to automate tasks, like testing and building of applications or websites, as well as create shareable and reproducible development environments.
Reproducible development environments allow team members to actively contribute to a shared code repository, each each team member using an identical compute environment by enabling the use of a containerized environment with devcontainers.
Github Actions
Personal website found here
- Uses a ‘on push’ trigger with github hosted runners
- the repository is checked out and cloned on the remote the ubuntu build machine (a gh hosted runner)
- install
quartoon the ubuntu build machine - use
quarto renderto build the website - the workflow artifacts (a tar archive of the rendered website files) are uploaded to a temporary server
- deploy the artifacts (rendered website) to the github pages URL
Gitpod Development Environment
I am working on the DevOps for Data Science lab exercises and recording the work in a github repository using
- environment is generated directly from a clone of the public repository
- a containerized environment is then built using Docker, which is orchestrated by GitPod Desktop
- automations are used to install required dependencies:
- a reproducible R environment is managed with Renv package to install R packages
- a reproducible Python environment is managed with venv library to install python packages
- the entire project and identical compute environment can be collaboratively developed using this link
Technical Skills and Courses
Databases and SQL
PostgreSQL databases built from schema design through to querying, in the coursework listed below.
Ongoing SQL study, with the relational database coursework below aimed at moving from queries against practice schemas to production use.
Additional details about technical skills, including course completion or course progress:
-
Git and Github
Docker
Linux
Python
SQL
AI and Data Scientist
Data Analyst
-
Postgres SQL Database: schema design, data import, and queries over tournament results
Postgres SQL Database: relational schema with foreign keys, joins, and aggregate queries
Postgres SQL Database: normalized multi-table schema built from the command line with
psqlAdditional course/module completions listed in my profile
-
- SQL programming course
- Introduction to SQL Queries and relational databases
- Completed: Nov 2024
- Introduction to Linux: Users and Permissions
- Useful refresher course
- Completed: Jan 2025
- SQL programming course
Hackathon Projects
2024 NF-Core Nextflow Hackathon
Created institutional profile on nf-core github
Added nf-validation tests to gunzip modules
2021 Bringing Genomics Data to the Clinic Hackathon
2018 Consensus Machine Learning for Gene Target Selection in Pediatric AML Risk: NCBI Hackathon
R Packages
- RNA-seq and multi-omics Data Analysis
R package was developed for use in the Meshinchi lab to help streamline the association of clinical covariates and RNA-seq and miRNA-seq expression data.
- RNA-seq Fusion Breakpoint Data Analysis
R package for Sequence Search in BAM files using R Bioconductor
Bioinformatics / Statistical Analysis Notebooks
The analysis notebooks (primarily Rmarkdown) for all analyses from Fred Hutch can be found at Meshinchi Lab. Selected analysis notebooks and scripts from SCRI are hosted at Research Scientific Computing github repository.
References
These pipelines and tools were used to reproducibly process data for many of the published journal articles on projects I supported. See the publications page for details.